













The AIOps Reality Check
By Brad Bell, Principal Observability Lead
The keynote demo is flawless. An anomaly appears, the platform’s AI identifies the root cause in seconds, drafts the fix, and remediates before a human would have finished reading the alert. The slide behind it says something about operations that run themselves, and the room full of people who got paged last night wants very badly to believe it.
I want to believe it too. I have carried “the pager”, and I teach SRE to teams who carry it now. Nobody is rooting harder for autonomous operations than the people it would let sleep.
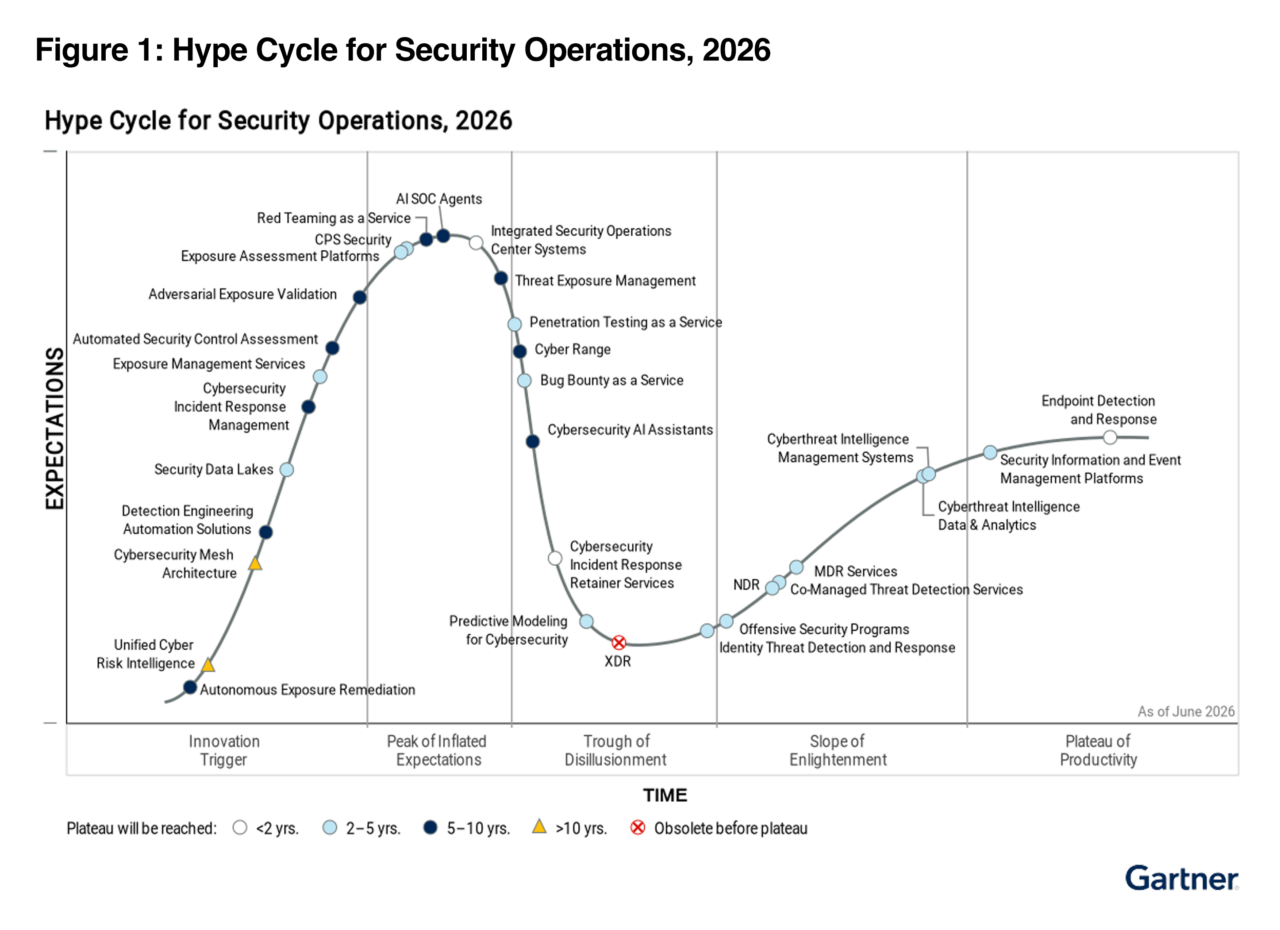
Which is exactly why this category deserves an honest accounting instead of either hype or dismissal. AI in operations crossed a real threshold over the past year: every major platform now ships capabilities that genuinely work. And the distance between what works and what the keynotes imply is still wide enough to lose a budget in. Here is the map as we see it from inside customer environments, mid-2026.
Give the machines their due
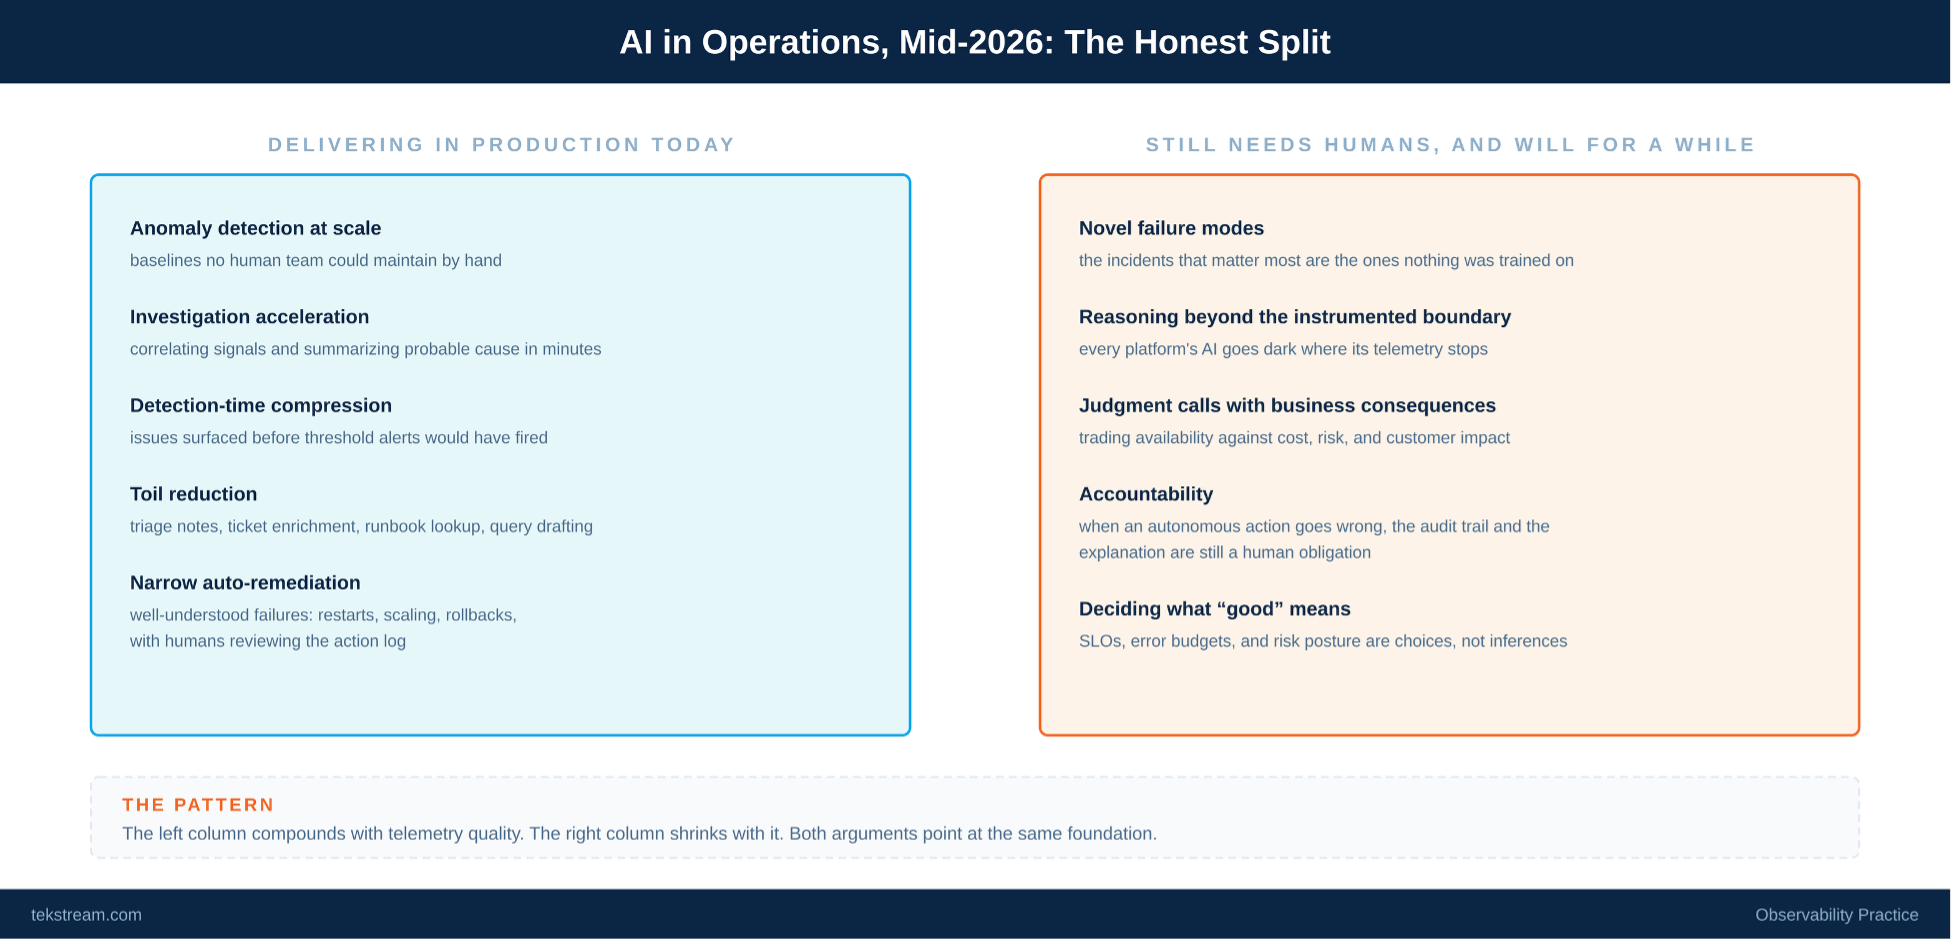
The dismissive take on AIOps is as wrong as the hype, so let’s start with what is real. Anomaly detection across thousands of services with learned baselines has quietly become table stakes; no human team maintains seasonal thresholds at that scale, and the machines genuinely do it better. Investigation acceleration is real: the current generation of operations AI correlates signals across telemetry domains and produces probable-cause summaries that compress the first thirty minutes of an incident into the first three. Detection-time gains are real. Toil reduction (triage notes, ticket enrichment, query drafting, runbook retrieval) is real and substantial.
The vendors have receipts. Dynatrace repositioned its entire platform this January around what it calls deterministic and agentic AI working together, grounded in its topology model. Datadog announced an autonomous tier of its Bits AI agents this month, spanning detection, investigation, and remediation. These are serious engineering organizations shipping serious capability, and pretending otherwise forfeits the credibility you need for the next part.
Where the demo and your estate part ways
The gap shows up in three places, and none of them is a missing feature.
- Autonomy handles the failures you already understand. Auto-remediation in production today is strongest on well-characterized failure modes: restart the stuck pod, scale the saturated pool, roll back the bad deploy. Valuable, genuinely. But the incidents that end up in your quarterly review are the novel ones, and novel is precisely what pattern-trained systems are worst at. The 3 AM page that matters most is the one nothing was trained on.
- Every platform’s AI reasons only over what that platform can see. This is the structural catch in even the best architectures. AI grounded in a causal topology model is genuinely more trustworthy than statistical correlation, and that grounding is also a boundary: the reasoning stops at the edge of the instrumented estate. Your environment is heterogeneous (acquisitions, legacy, SaaS, the cluster nobody migrated), and the AI’s confidence does not drop at the boundary. Its correctness does.
- Autonomous action creates an accountability question faster than it creates an accountability answer. When an automated remediation makes things worse, someone still owes the business an explanation. “What did the system do, on what evidence, and why” needs a reviewable record, and in regulated environments that record is not optional. Ask any vendor demoing autonomy to show you the decision audit trail. The quality of the answer tells you how production-ready the autonomy actually is.
The dependency the keynotes skip
Underneath all three gaps sits the same unglamorous truth: AI-driven operations are exactly as good as the telemetry they reason over, and not one bit better.
Feed an operations AI incomplete instrumentation and it will reason confidently inside its blind spots. Feed it noisy alerts and it learns your noise. Feed it metrics with inconsistent naming, traces with broken context propagation, and logs nobody structured, and you have not automated your operations. You have automated your operations’ bad habits, at machine speed, with a confident summary attached.
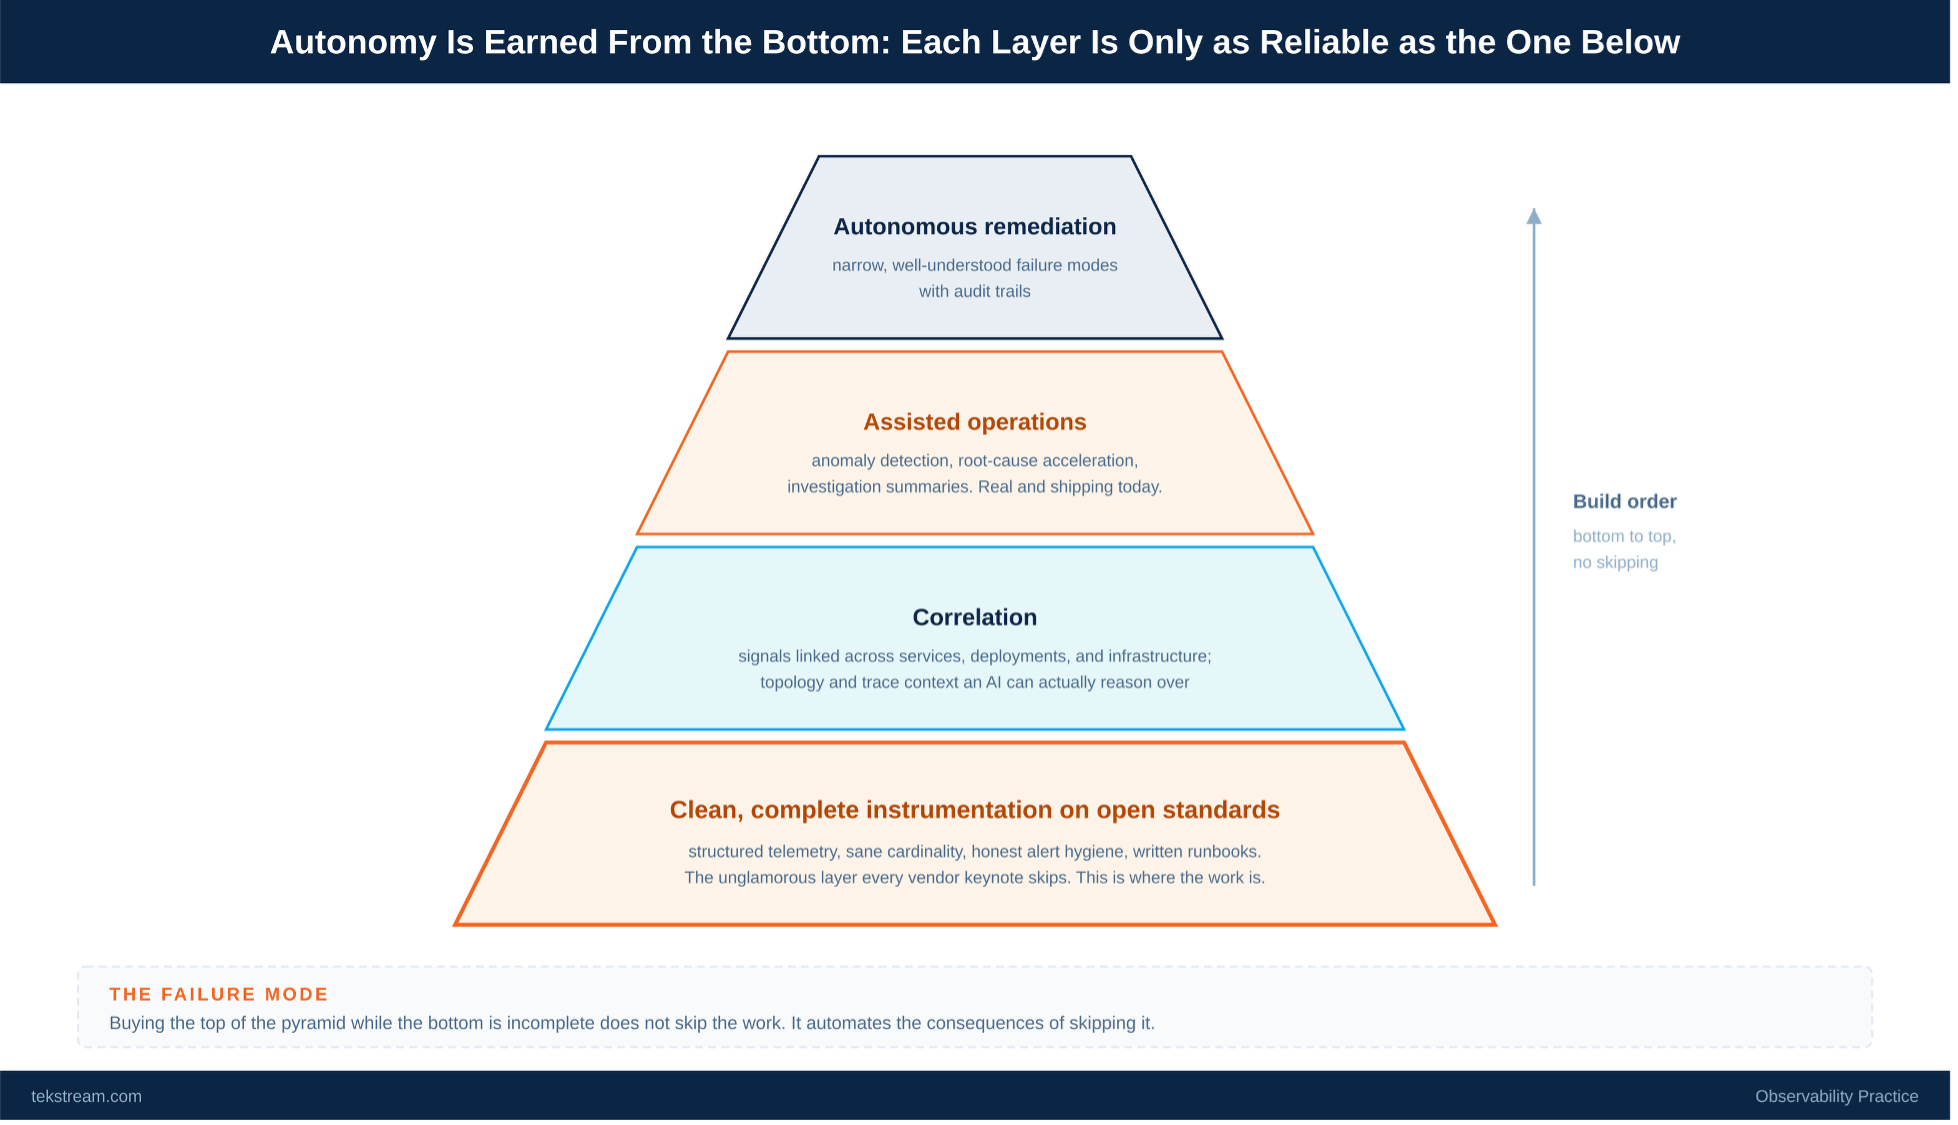
This is the part nobody puts on a slide, because the foundation is not a product you can sell in a keynote. It is structured telemetry on open standards. Sane cardinality. Alert hygiene honest enough that a signal means something. Runbooks that exist in writing, because a remediation AI cannot learn tribal knowledge that lives in someone’s head. Service ownership that is actually recorded somewhere. None of it demos well. All of it determines whether the impressive thing you bought works in your environment or just in the vendor’s.
Autonomy is earned, not installed
The pyramid is the operating advice. Clean instrumentation at the bottom, correlation above it, assisted operations above that, and autonomous remediation at the top, scoped narrow and audited. Build in that order and each layer makes the next one trustworthy. Buy the top while the bottom is incomplete and you have not skipped the work; you have automated the consequences of skipping it.
In practice, the build order looks like this. Instrument on open standards first, including your AI workloads themselves, because agents and RAG pipelines are production systems that need the same five signals as everything else. Fix alert hygiene second; an AI triaging a thousand meaningless alerts learns that alerts are meaningless. Write the runbooks third, because they become the training material for whatever assists you later. Then turn on assisted operations and let it earn trust on investigations before it touches anything. Autonomy comes last, one well-understood failure mode at a time, each with a decision log a human reviews.
Teams that follow this order report something the keynotes get right for the wrong reason: the AI really does change on-call. Not because it runs operations alone, but because the humans stop spending their judgment on toil and spend it on the novel failures where judgment is the whole game.
The question to take into your next vendor meeting
So when the autonomous-operations pitch arrives (and if it has not yet, it is on the calendar), the productive response is not skepticism or surrender. It is two questions. What share of our estate does your platform actually see, mapped honestly? And when your AI acts, what is the reviewable record of why? Strong answers to both mean the capability is worth piloting on your most boring failure mode. Weak answers mean you have found the work to do first, and it was always going to be the foundation.
In our experience the organizations that win the next two years of this market will not be the ones that bought the most AI. They will be the ones whose telemetry was worth automating on. If you want a fast read on which one you are, our three-minute self-assessment scores the five signals that foundation depends on; it is a fair first step whether the next move involves us or not.
About the Author
Brad Bell is the Principal Observability Lead at TekStream Solutions, a Digital Resilience partner that helps organizations operate, recover, and adapt with confidence by modernizing, securing, and optimizing their digital environments. His 29 years of experience spans large-scale telecommunications infrastructure, enterprise cloud strategy, and operational transformation across industries ranging from financial services to quick-service restaurants — work that included scaling monitoring platforms to 12,000+ nodes, architecting next-generation networks, and turning reactive ops teams into reliability engineering organizations. A Grafana Certified Solutions Architect and PreSales Solution Architect, he teaches SRE immersion courses at major financial institutions and consults on observability strategy at the enterprise level, helping clients navigate the convergence of cost pressure, tool sprawl, and AI-driven operations that is reshaping how enterprises think about reliability. His perspective isn’t theoretical — it comes from having been the person on the other end of a 2 AM page, and from watching organizations make expensive, avoidable mistakes with their observability investments. At TekStream, his focus is helping enterprises build platforms that solve today’s problems and hold up against where the industry is headed.