













Your AI Has an Uptime SLO. It Needs a Correctness One.
By Brad Bell, Principal Observability Lead
A fast, available, confidently wrong answer scores a perfect 100% on an availability SLO. How to point the SRE machinery you already trust at correctness instead of uptime.
Here is a service level objective I have seen on real dashboards for real AI assistants: the agent responds in under two seconds, ninety-nine point nine percent of the time. It is measured precisely, alerted on properly, and reviewed in the operations meeting. It is also measuring a promise that no user has ever cared about.
Nobody wants a fast answer. They want a right answer, delivered fast. An SLO that tracks only the second half of that sentence is monitoring the part that was never the point, and it will sit at a comfortable green while the assistant confidently tells customers the wrong thing. Fast and available and wrong is a perfect score on an availability SLO. That is not a measurement problem at the edges. That is the SLO measuring the wrong thing entirely.
The short version: Availability and latency SLOs are proxies for user happiness that break for AI, because a language model can return a fast, successful, completely wrong answer with no transport-layer signal flickering. The fix is a correctness SLO: keep the same SRE machinery, error budgets, burn-rate alerts, release gates, and swap the indicator for a quality score on production traffic. Start with one SLI in the family that maps to how your AI hurts the business when it fails.
The fix is not to abandon SLOs. It is to point the discipline you already trust at the promise your AI actually makes. And the good news, for anyone who has stood up an availability SLO, is that you already own most of the machinery.
Why does availability quietly fail for AI?
Traditional SLOs work because the things they measure are proxies for user happiness that happen to be easy to instrument. A 500 means a user did not get what they asked for. A ten-second latency means a user gave up. Availability and latency are not what users care about in themselves; they are cheap, reliable stand-ins for what users care about, which is getting a useful result.
For deterministic software, that proxy holds. If the request succeeded and returned fast, the user almost certainly got a correct result, because the logic is fixed and tested. AI breaks the proxy. A large language model can return a perfectly formed, sub-second, HTTP 200 response that is completely wrong, and nothing about the transport-layer signals will so much as flicker. The proxy that made availability a good-enough measure of happiness simply does not transfer.
So the work is to find a new proxy: a signal that actually tracks whether the AI did its job, and that you can measure on live traffic. That signal is a quality score, and once you have it, the rest of the SLO apparatus snaps right on.
The anatomy transfers almost unchanged
Walk the pieces. An availability SLO has a service level indicator (did the request succeed, fast enough), an objective (the percentage that must), an error budget (how much failure you will tolerate before you stop shipping features and start fixing reliability), and the operational machinery that hangs off the budget: burn-rate alerts, release gates, postmortems with a number attached.

Figure 1. The skeleton is identical. Swap the indicator from request success to a quality score on production traffic, and the error budgets, alerts, and gates work unchanged.
A correctness SLO has exactly the same skeleton. The indicator becomes a quality score on production traffic. The objective becomes the share of answers that must score above a line you choose on purpose. The error budget becomes a quality budget, burned by wrong, ungrounded, or unsafe answers instead of by bad minutes. And every piece of operational machinery you built for availability (the burn-rate math, the alerting, the gating, the review ritual) works without modification, because it never cared what the underlying SLI measured. It only ever cared about a number crossing a line.
That is the part worth sitting with. The hard-won SRE infrastructure in your organization is not availability infrastructure. It is objective infrastructure, and it will happily enforce a correctness objective the moment you can produce the score.
The genuinely hard part: defining quality
Which is where the real work lives, and I will not pretend otherwise. Quality score on production traffic is a clean phrase hiding two thorny questions: what does a good answer mean for this specific AI, and who or what assigns the score at production volume.
The first question is a product question wearing an engineering costume. Correctness for a customer-support assistant means grounded in the actual policy and accurate. Correctness for a coding agent means the code runs and does what was asked. Correctness for a summarization feature means faithful to the source with nothing invented. You cannot define the SLI until someone decides what the AI is actually promising, and that conversation usually surfaces the uncomfortable fact that nobody had written it down.
The second question is the measurement question. You cannot put a human on every production response, so the scoring comes from some combination of automated evaluators: programmatic checks where the answer has verifiable structure, model-based evaluation (the LLM-as-judge pattern) where it does not, and human review on a sampled slice to keep the automated scores honest. That last clause is not optional. An LLM-as-judge drifts exactly like the model it scores; an uncalibrated judge gives you a confident quality number that is its own kind of hallucination. Calibration against human-labeled samples, on a schedule, is the price of trusting the SLI at all.
Four families, and the discipline to start with one
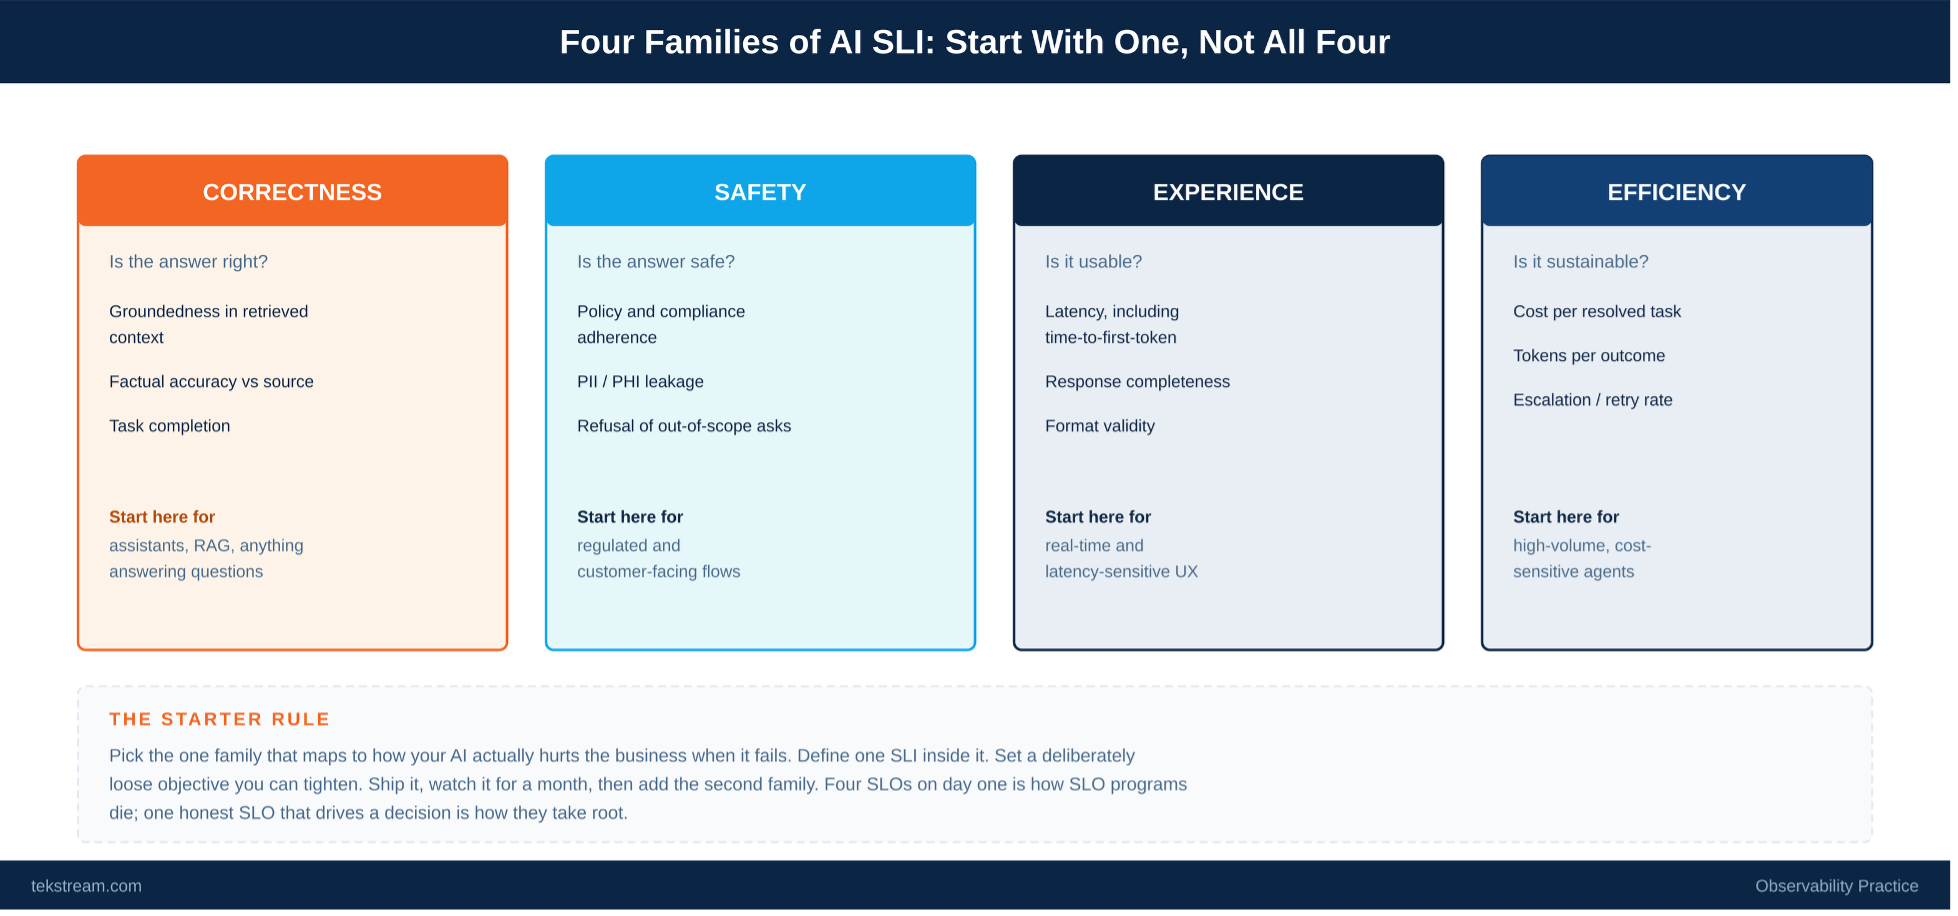
Figure 2. AI SLIs cluster into four families. Pick the one that maps to how your AI hurts the business when it fails, and define a single indicator inside it.
Quality is not one dimension, and the failure mode of eager teams is trying to measure all of it at once. In practice AI SLIs cluster into four families.
Correctness asks whether the answer is right: groundedness, factual accuracy, task completion. Safety asks whether it is allowed: policy adherence, data leakage, appropriate refusals. Experience asks whether it is usable: latency including time-to-first-token, completeness, valid format. Efficiency asks whether it is sustainable: cost per resolved task, tokens per outcome, retry and escalation rates. Most AI systems eventually want indicators from more than one family, and almost none should start that way.
Pick the single family that maps to how your AI actually hurts the business when it fails. Define one SLI inside it. Set the objective deliberately loose at first, because you would rather tighten a target you are hitting than miss one you set by guessing. Ship it, watch it for a month, learn what it does to behavior, then add the second family. Four SLOs on day one is how SLO programs collapse under their own ceremony. One honest SLO that actually drives a decision is how they take root and earn the right to grow.
What changes once it exists
A correctness SLO does something an availability SLO never could: it makes quality a shared, operational number instead of an anecdote. Today, in most organizations, AI quality is litigated through screenshots in a Slack channel and gut feeling in a planning meeting. Once there is an SLI, a target, and a budget, quality enters the same operational reality as everything else you run. A release that degrades answers trips a gate. A slow quality decline burns budget and alerts before it becomes a customer story. A postmortem cites the number instead of the vibe.
It also reframes the build-versus-buy and model-selection arguments that AI teams run in circles on. Which model is better is unanswerable in the abstract and trivial against a defined SLI: you measure both against the objective that encodes what you actually need. The SLO turns taste debates into measurements.
Start before you feel ready
The objection I hear most is that the organization is not mature enough for AI SLOs yet. It is backwards. We built availability SLOs while we were still figuring out distributed systems, and the SLOs were part of how we figured them out. The same is true here. You do not earn the right to a correctness SLO by achieving quality first; you achieve quality, in part, by committing to a number and letting it pull the rest of the practice forward.
The honest prerequisite is not maturity. It is a quality signal you can measure on production traffic, which means instrumentation: the generation data, the conversation traces, and the evaluation scores that make a quality SLI possible at all. If you are not sure whether you have that foundation, that is worth finding out before you write the objective. Our three-minute self-assessment scores exactly those signals, and it is a reasonable place to learn whether your next move is writing an SLO or building the telemetry one would stand on.
About the Author
Brad Bell is the Principal Observability Lead at TekStream Solutions, a Digital Resilience partner that helps organizations operate, recover, and adapt with confidence by modernizing, securing, and optimizing their digital environments. His 29 years of experience spans large-scale telecommunications infrastructure, enterprise cloud strategy, and operational transformation across industries ranging from financial services to quick-service restaurants — work that included scaling monitoring platforms to 12,000+ nodes, architecting next-generation networks, and turning reactive ops teams into reliability engineering organizations. A Grafana Certified Solutions Architect and PreSales Solution Architect, he teaches SRE immersion courses at major financial institutions and consults on observability strategy at the enterprise level, helping clients navigate the convergence of cost pressure, tool sprawl, and AI-driven operations that is reshaping how enterprises think about reliability. His perspective isn’t theoretical — it comes from having been the person on the other end of a 2 AM page, and from watching organizations make expensive, avoidable mistakes with their observability investments. At TekStream, his focus is helping enterprises build platforms that solve today’s problems and hold up against where the industry is headed.