













Token Costs Are the New Per-Host Pricing
By Brad Bell, Principal Observability Lead
Quick question, and answer it honestly before you read on: what does your AI cost per conversation?
Not the monthly total. Everyone knows the monthly total, because the invoice announces it in a number large enough to get forwarded to a vice president. Per conversation. Per feature. Per team. If you just paused, you are in excellent company, and you are also looking at a movie you have already seen twice.
The short version: Usage-based AI token pricing repeats the per-host and per-gigabyte pattern: cost detaches from any plannable quantity, drifts upward unowned, and lands as an invoice shock followed by a blunt cut. Two things make the token version worse, agentic call patterns compound spend, and the waste is invisible. The advantage you did not have before: the OpenTelemetry gen_ai conventions carry cost as a first-class signal, so attribution can be a design choice instead of a forensic reconstruction.
Anyone who ran infrastructure through the last decade lived this exact story with monitoring spend, then again with log volume. A new cost category arrives priced by usage. It grows quietly inside a budget line nobody owns. An invoice eventually lands hard enough to trigger a fire drill. And then comes the worst part: a frantic, after-the-fact project to figure out who and what was actually driving the spend, on a system that was never instrumented to tell you. Token spend is that story for a third time, and the only real question is whether you write a different ending.
Why does this rhyme so precisely?
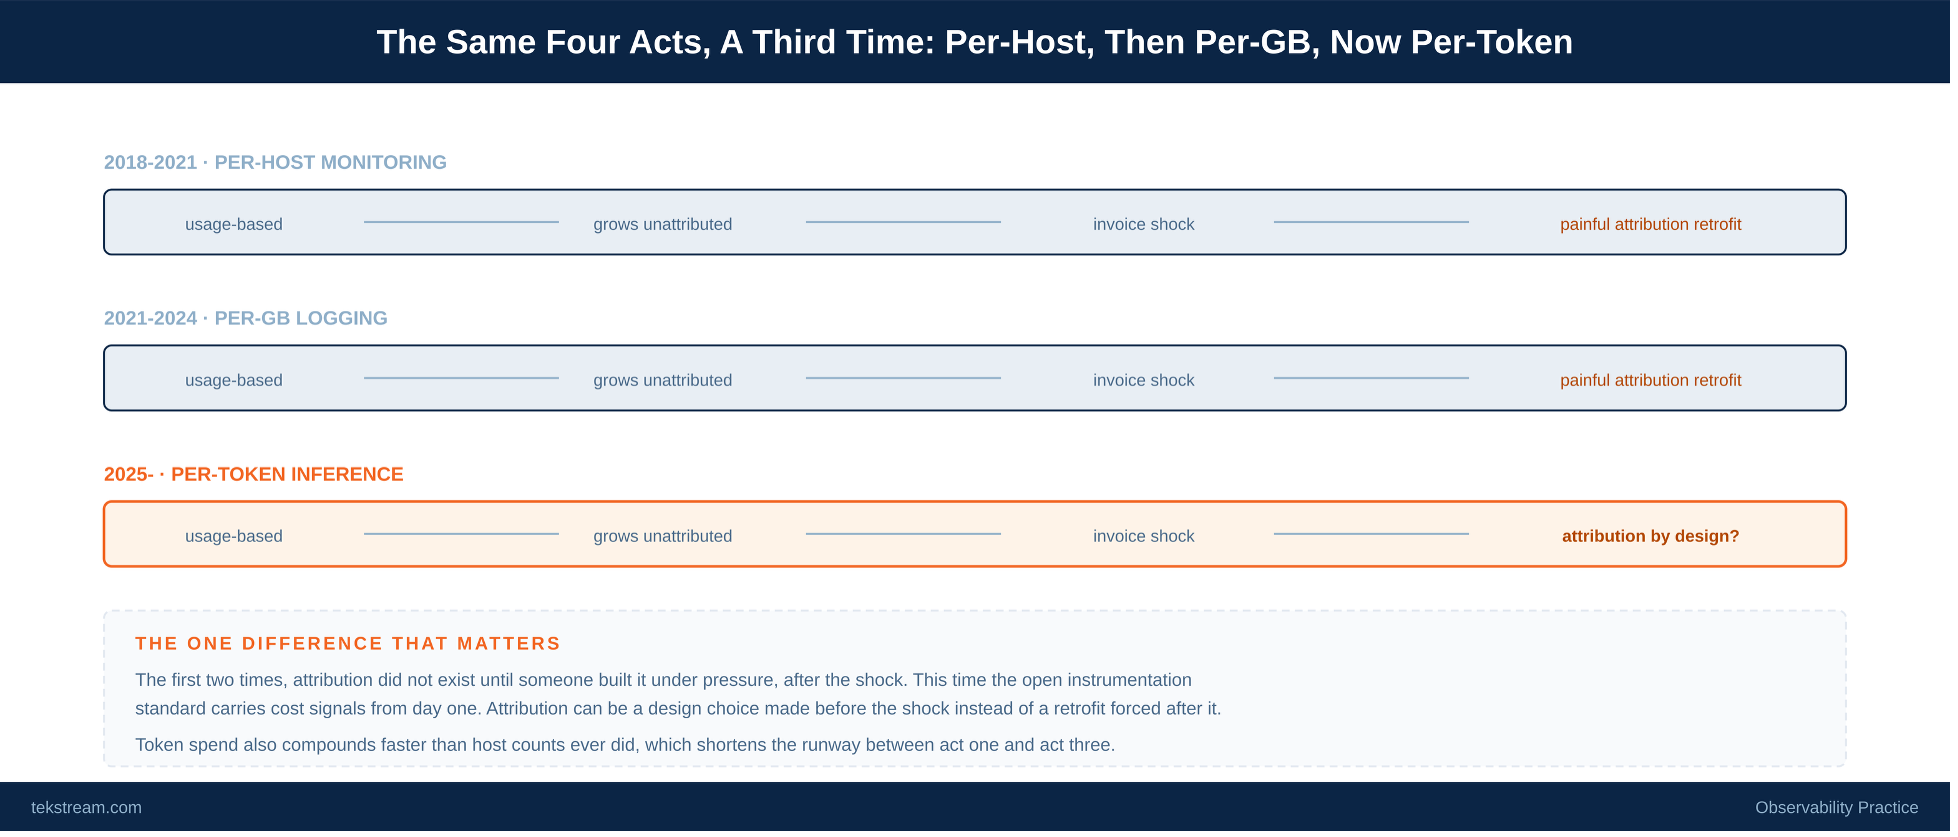
Figure 1. The same four acts, a third time. Per-host, then per-gigabyte, now per-token, each running usage-based to invoice shock to a blunt retrofit.
The mechanism is identical across all three waves, which is why the outcome is so predictable. Usage-based pricing detaches cost from any fixed, plannable quantity. With a per-seat license you know the bill; with per-host, per-gigabyte, or per-token pricing, the bill is an emergent property of behavior, and behavior drifts upward by default. A team adds a feature. Another widens a prompt. Traffic grows. Nobody decided to spend more; the spend simply accreted, and the invoice is the first time anyone sees the sum.
The reason it hurts is not the size of the number. It is the absence of attribution. A large bill you can decompose is a management decision: you can see which workloads earn their cost and prune the ones that do not. A large bill you cannot decompose is a panic, and panic produces blunt instruments. Someone mandates a blanket reduction, the cut lands on valuable usage and waste alike, and a quarter later the same dynamic is back because nothing structural changed.
Two things make the token version worse
If this were merely a rerun, you could dust off the playbook from last time. Two differences make AI inference spend a faster and nastier version of the pattern.
- It compounds in ways host counts never did. A host serves a roughly bounded amount of work. An agent can call itself, retry, fan out to sub-agents, and loop, so a single user request can spawn dozens of model calls. Agentic architectures turn linear traffic growth into something closer to multiplicative cost growth, which shortens the runway between the feature launch and the invoice shock from years to months.
- The waste is invisible and often enormous. With hosts you could at least see idle capacity. Token waste hides: prompts that grew bloated through copy-paste, caching that was never turned on, an expensive frontier model handling requests a model a tenth the price would answer identically, retry storms that burn budget producing nothing. None of it shows up without attribution, and all of it is the cheapest spend to eliminate once you can see it.
The one advantage you did not have before
Here is the genuinely good news, and it is the reason this ending can differ from the last two. Both previous times, attribution did not exist until someone built it under duress. There was no standard; every team improvised tagging schemes after the shock, badly, against the clock.
This time the instrumentation standard exists before the shock. The OpenTelemetry gen_ai semantic conventions carry cost signals as a first-class part of AI telemetry: token counts in and out, model and provider, and the trace context that ties spend to the feature, team, and conversation that incurred it. Attribution can be a design choice you make on the way in, rather than a forensic reconstruction you attempt on the way out. The teams that instrument cost as one of their AI signals from the start simply never have the act-three fire drill. They were watching the curve the whole time.
What does cost attribution actually buy you?
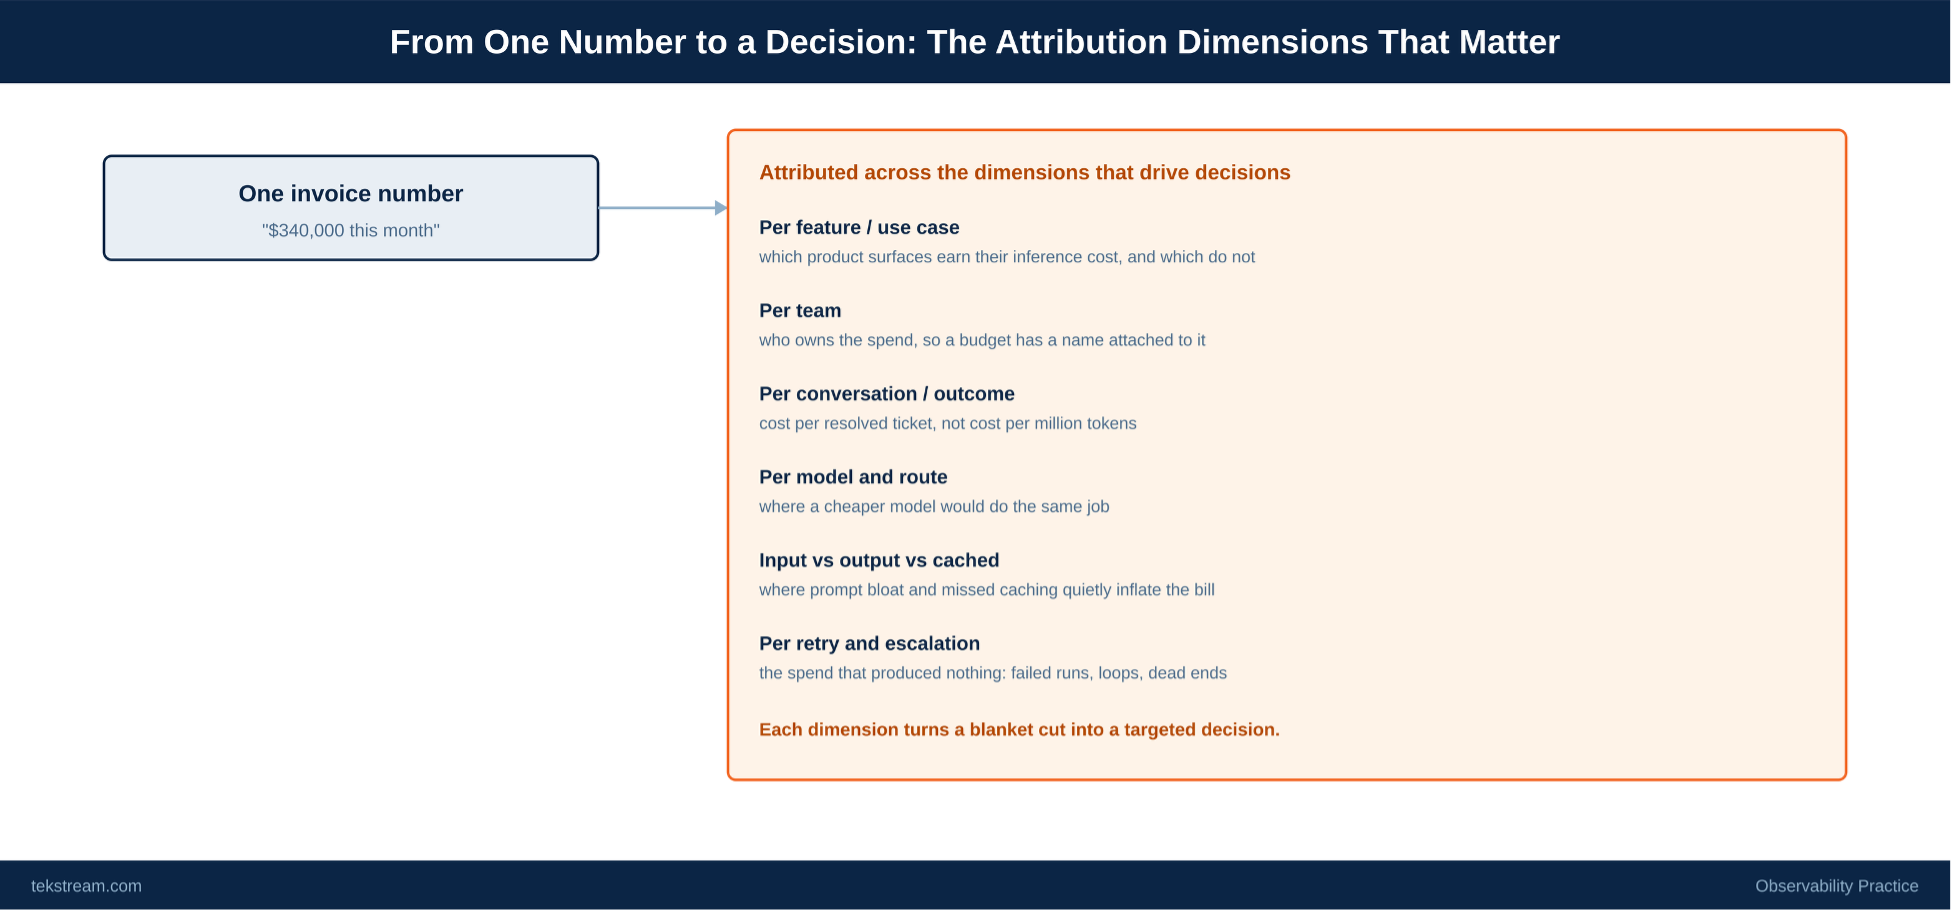
Figure 2. Each dimension you can slice turns a blunt cost panic into a specific, defensible decision.
Attribution is not a reporting nicety. Each dimension you can slice converts a blunt cost panic into a specific, defensible decision.
Cost per feature tells you which product surfaces earn their inference and which are quietly subsidized. Cost per team puts a name on a budget, which is the difference between a number that drifts and a number someone owns. Cost per conversation or resolved outcome is the metric that actually matters: not dollars per million tokens, but dollars per ticket resolved, which is the only framing that lets you reason about whether the AI is worth what it costs. Cost per model and route surfaces the requests overpaying for capability they do not need. The input-output-cached split exposes prompt bloat and missed caching. And cost per retry and escalation reveals the spend that produced nothing at all, which is usually the first thing worth cutting because no one defends it.
Notice that none of these is a cost-cutting tool in the crude sense. They are decision tools. The point of attribution is not to spend less; it is to spend deliberately, which sometimes means spending more on the workflow that earns it and zeroing the one that does not.
Where this meets the rest of observability
Cost attribution is one of the five signals that make an AI system observable, and it is not even the one that prevents the worst incidents. But it is frequently the one that opens the conversation, because it is the signal a finance-aware executive feels first and fastest. An organization that cannot attribute its inference spend almost certainly cannot see its retrieval quality or score its answers either; the invoice is just the most legible symptom of a system that was shipped without observability. In our experience, the cost question is often the door, and the rooms it opens into are the ones where quality and reliability actually live.
That connection cuts the other way too. The same instrumentation that attributes cost also carries the conversation traces and generation data that make quality measurable. You are not building a cost system and a quality system; you are building one observability layer that happens to answer both questions. Teams that frame it as a FinOps project alone tend to bolt on narrow cost tracking and miss that they were one short step from seeing whether the expensive answers were even correct.
Write the different ending
If you cannot currently state your AI cost per conversation, you are somewhere in act two, and act three arrives on its own schedule whether or not you prepare for it. The move that changes the story is not a spending freeze. It is instrumenting cost attribution now, as a design choice, while the runway still exists, so the next surprising invoice arrives with an answer attached instead of a fire drill.
The fastest way to find out where you stand is to ask the question this post opened with, across your organization, and watch who can answer it. Our three-minute self-assessment scores cost attribution alongside the four other AI signals; it will tell you, fairly and quickly, whether your next move is optimization or instrumentation. And if you have lived the per-host or per-gigabyte version of this story before, you already know which ending you would rather have.
Frequently asked questions
Why is AI token cost so hard to control?
Because usage-based pricing detaches cost from any plannable quantity. Spend becomes an emergent property of behavior that drifts upward as teams add features and widen prompts, and without attribution the first time anyone sees the sum is the invoice. Agentic call patterns make it worse by turning one request into dozens of model calls.
What is AI cost attribution?
Cost attribution is instrumenting AI spend so you can slice it by feature, team, conversation, model and route, the input-output-cached split, and retries. It converts a single monthly invoice number into specific, defensible decisions about which workloads earn their inference and which are waste.
How do you track cost per AI conversation?
Capture cost as a first-class telemetry signal using the OpenTelemetry gen_ai semantic conventions: token counts in and out, model and provider, and the trace context that ties spend to the conversation, feature, and team that incurred it. Done at instrumentation time, cost per conversation and cost per resolved outcome become a query rather than a forensic project.
Is cost attribution just a FinOps concern?
No. The same instrumentation that attributes cost also carries the conversation traces and generation data that make answer quality measurable. Teams that treat it as a standalone FinOps project tend to bolt on narrow cost tracking and miss that they were one step from seeing whether their expensive answers were even correct.
About the Author
Brad Bell is the Principal Observability Lead at TekStream Solutions, a Digital Resilience partner that helps organizations operate, recover, and adapt with confidence by modernizing, securing, and optimizing their digital environments. His 29 years of experience spans large-scale telecommunications infrastructure, enterprise cloud strategy, and operational transformation across industries ranging from financial services to quick-service restaurants — work that included scaling monitoring platforms to 12,000+ nodes, architecting next-generation networks, and turning reactive ops teams into reliability engineering organizations. A Grafana Certified Solutions Architect and PreSales Solution Architect, he teaches SRE immersion courses at major financial institutions and consults on observability strategy at the enterprise level, helping clients navigate the convergence of cost pressure, tool sprawl, and AI-driven operations that is reshaping how enterprises think about reliability. His perspective isn’t theoretical — it comes from having been the person on the other end of a 2 AM page, and from watching organizations make expensive, avoidable mistakes with their observability investments. At TekStream, his focus is helping enterprises build platforms that solve today’s problems and hold up against where the industry is headed.