












Retrieval Observability: A Practical How-To
By Brad Bell, Principal Observability Lead
The companion build plan to the retrieval-failures piece. What to capture at each step of a RAG pipeline, on the open standard, and how to ship value one self-justifying step at a time.
If you have read our piece on why RAG failures look like model failures, you know the diagnosis: most wrong answers in retrieval-augmented systems originate upstream of the model, in a retrieval pipeline almost nobody instruments. This is the companion piece, and it answers the obvious next question. Fine, so how do we actually see retrieval? What do we capture, where, and what do we do with it once we have it?
The short version: Instrument retrieval as a trace, not a black box: a sequence of spans (embed, search, rerank, assemble context), all children of the conversation trace. At each step capture document IDs and similarity scores, freshness, filters, and what got truncated, on the OpenTelemetry gen_ai conventions so the telemetry is portable. Start with document IDs and scores at the search step, the highest-value, lowest-effort move, then add freshness, groundedness scoring, and trends.
This is a practitioner’s how-to, written for the engineer who has accepted that the retrieval pipeline is a production system and now has to instrument it. It assumes you know what a span is and have at least a passing relationship with OpenTelemetry. It does not assume you have done this for AI workloads before, because most people have not.
The mental model: retrieval is a trace, not a black box
The single most useful shift is to stop thinking of retrieval as one opaque step that returns some documents and start thinking of it as a sequence of instrumented operations, each one a span, all of them children of the conversation trace. A user question enters, gets embedded, searches a store, the candidates get reranked, a context window gets assembled, and only then does the model see anything. Each of those is a discrete operation that can be timed, measured, and recorded, and the failures hide in the seams between them.
Once retrieval is a trace rather than a black box, debugging a bad answer changes character completely. Instead of guessing whether the model or the retrieval was at fault, you open the trace for that exact request and walk it backward: here is the response, here is the context it was given, here is what reranking did to the candidate order, here is what the store returned, here is how the query was embedded. The wrong context, if that is what happened, is visible at the exact step it entered.
What to capture at each step
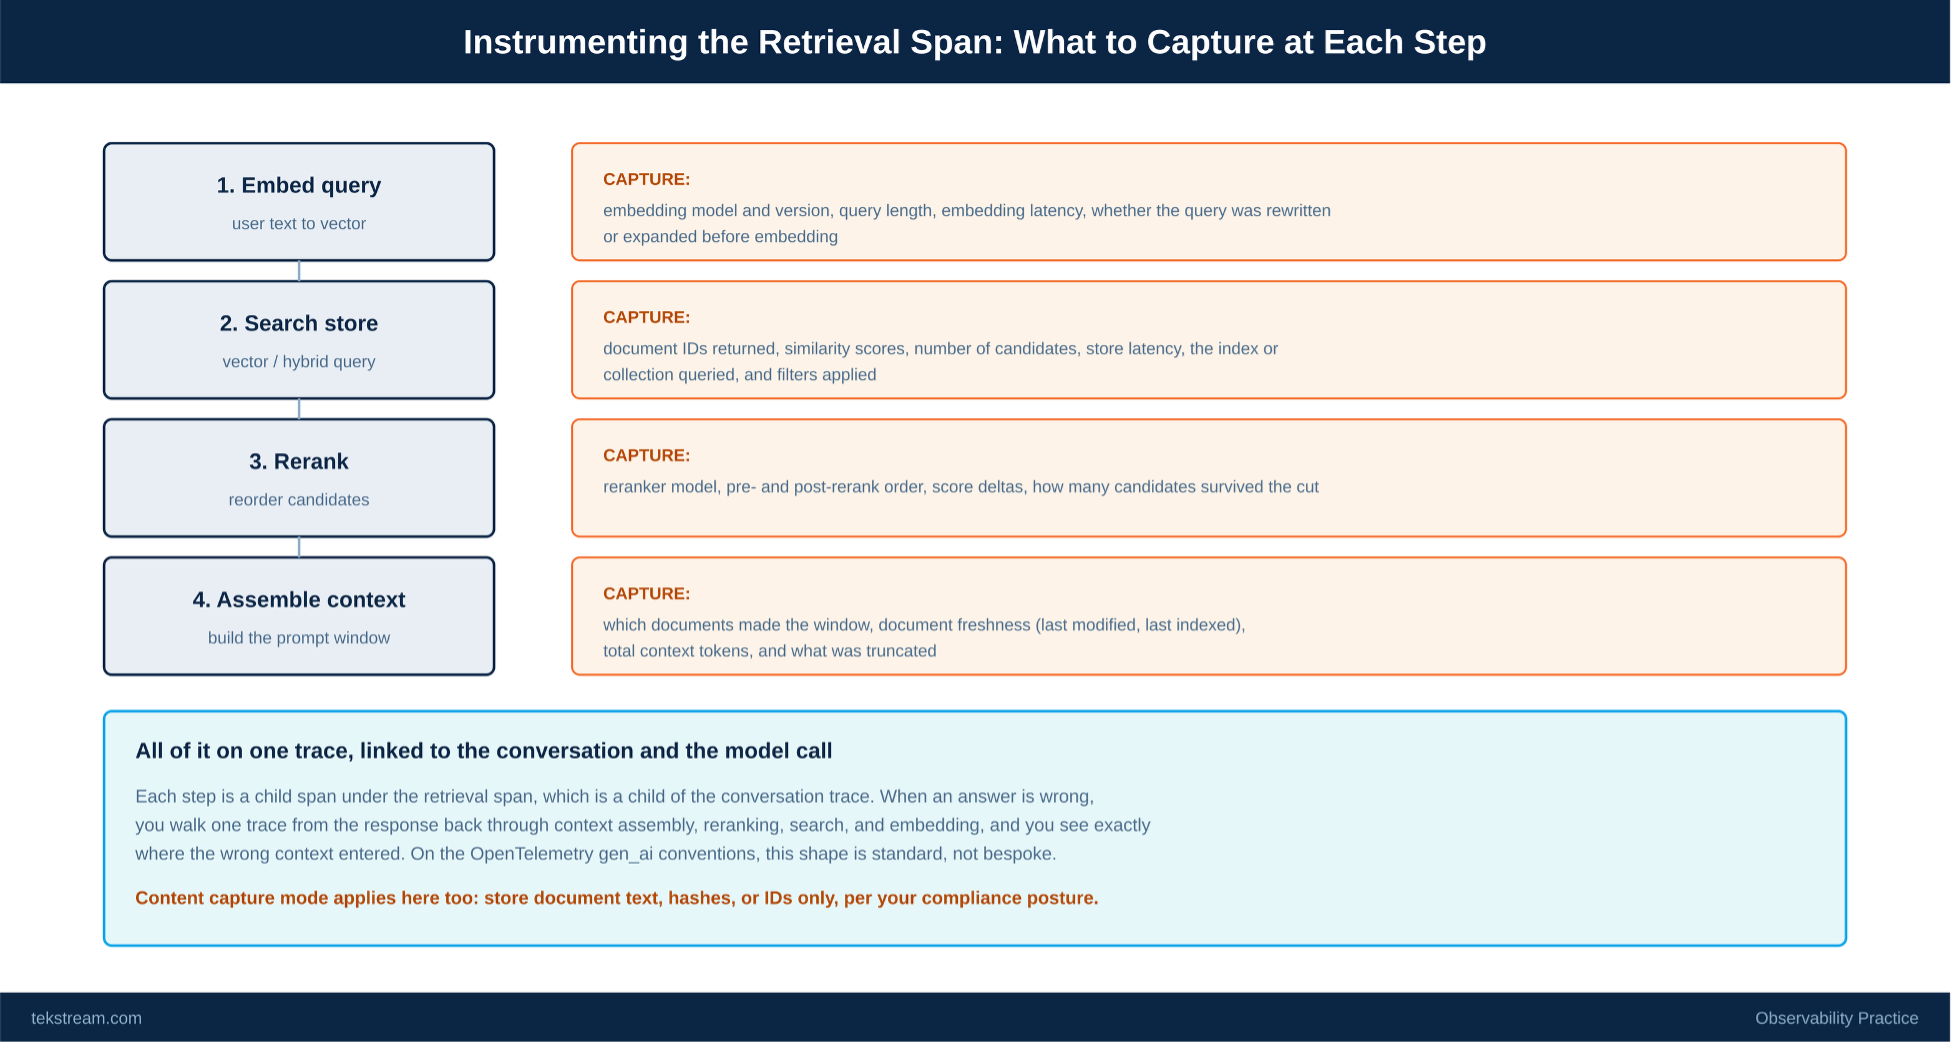
Figure 1. Instrument each operation as a span, linked to the conversation and the model call, on the OpenTelemetry gen_ai conventions.
Walk the pipeline and instrument each operation. At the embedding step, record the embedding model and version, the query length, the embedding latency, and crucially whether the query was rewritten or expanded before embedding, because query transformation is a common and invisible source of retrieval misses. At the search step, capture the document identifiers returned, their similarity scores, the number of candidates, the store latency, which index or collection was queried, and any filters applied; the filters matter more than people expect, because a permissions or metadata filter quietly excluding the best documents is a classic silent failure.
At the rerank step, if you have one, record the reranker model, the candidate order before and after, the score deltas, and how many candidates survived the cut. At the context assembly step, capture which documents actually made it into the prompt window, their freshness (when each was last modified and last indexed), the total context tokens, and what got truncated. Truncation is the failure mode that surprises people most: the right document was retrieved, ranked well, and then trimmed out of the window by a token budget nobody was watching.
Two cross-cutting practices make all of this usable. Link every retrieval span to the conversation trace and the downstream model call, so one bad answer unrolls into its complete causal chain rather than a pile of disconnected spans. And apply your content capture mode here exactly as you would for generation data: store full document text where compliance allows, hashes or identifiers where it does not, decided per workload. Retrieval telemetry is subject to the same data-handling discipline as everything else, and treating it that way from the start saves a painful retrofit.
Use the standard, not a homegrown schema
Resist the urge to invent your own span attributes. The OpenTelemetry gen_ai semantic conventions give retrieval operations a standard shape, and the major frameworks (the popular orchestration and RAG libraries) emit much of this telemetry with configuration rather than custom code. In many stacks, turning on the framework’s OpenTelemetry integration gets you embedding and search spans for free, and your job becomes enriching them with the relevance, freshness, and groundedness signals the framework does not know to capture.
The reason this matters beyond convenience: telemetry on the standard is portable telemetry. Instrument retrieval on the gen_ai conventions and the data flows into any compatible backend, feeds automated evaluation later without rework, and survives whatever tooling decision you make next. Instrument it with a bespoke schema and you have built something that works only with the code that emits it, which is the same lock-in trap in miniature that the whole campaign warns about. Use the standard.
From spans to answers
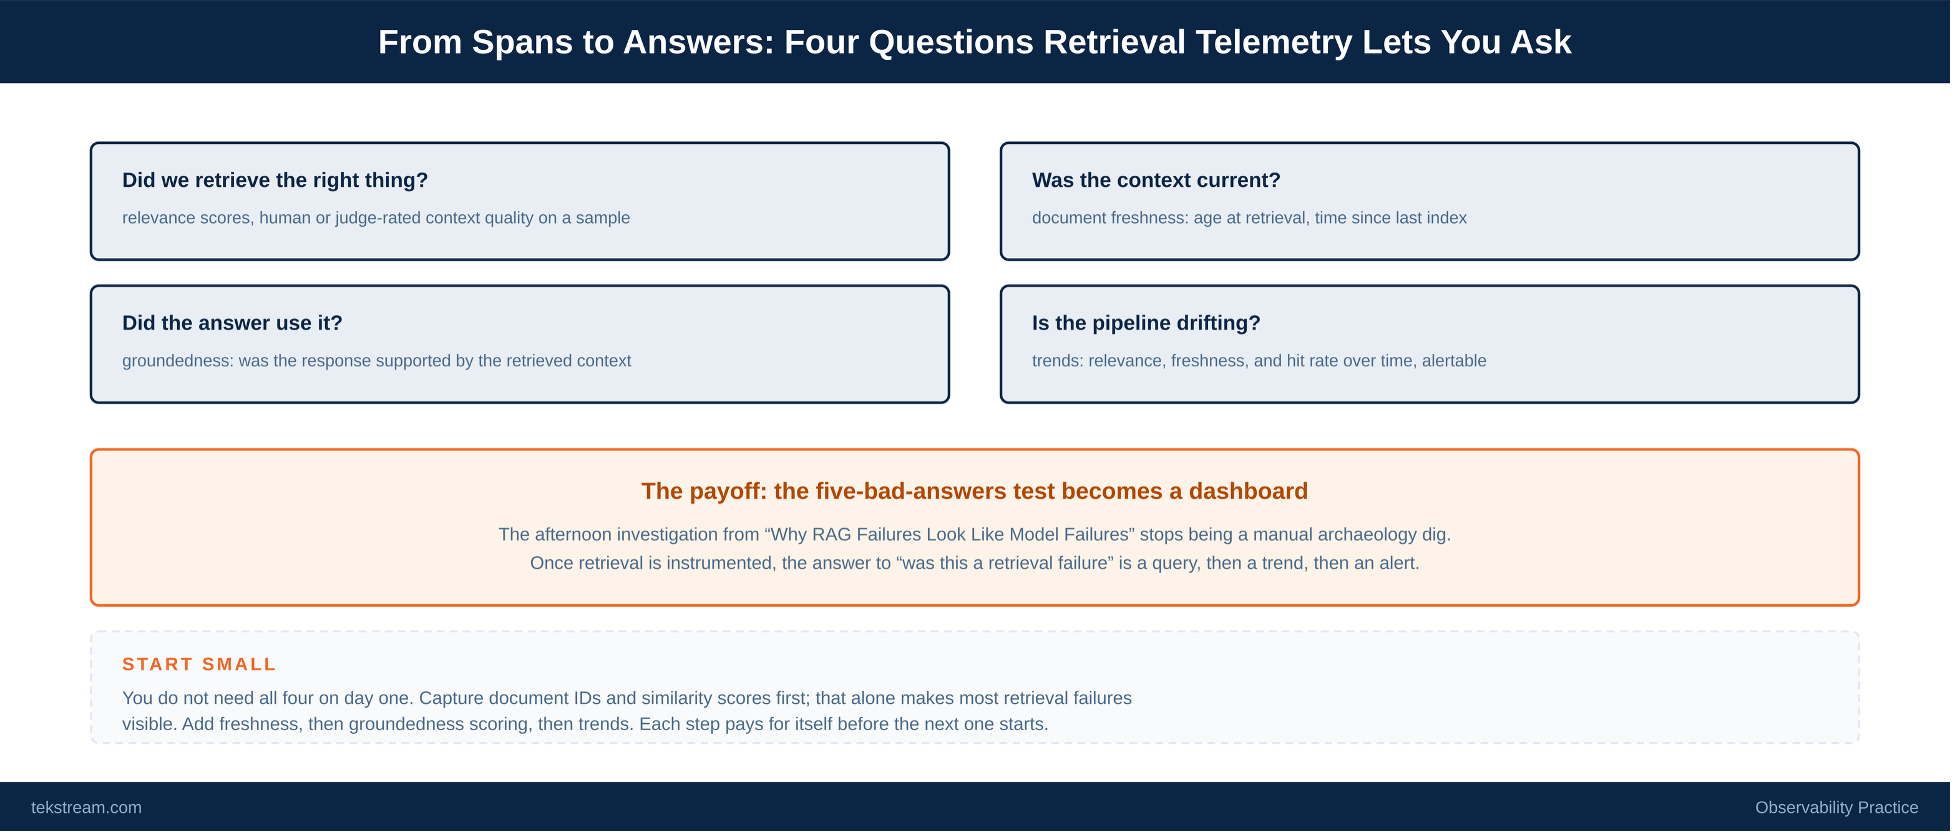
Figure 2. Once the spans exist, four questions that were unanswerable become routine, and the five-bad-answers test becomes a dashboard.
Captured telemetry is not the goal; answered questions are. Once the spans exist, four questions that were unanswerable become routine.
Did we retrieve the right thing? Relevance scores from the retriever and reranker give you a first cut, and a judge or human rating of context quality on a sample gives you ground truth. Was the context current? Document freshness, captured at retrieval time, turns staleness from an invisible failure into a measurable and alertable one. Did the answer actually use the context? Groundedness scoring, comparing the response against the retrieved documents, separates a retrieval problem from a model that ignored good context, which are different failures with different fixes. And is the pipeline drifting? Trended over time, relevance and freshness and hit rate expose slow degradation (an index falling behind, an embedding model aging, a corpus growing stale) before it becomes an incident.
The payoff is the one promised in the first piece: the five-bad-answers test stops being a manual archaeology dig and becomes a dashboard. Was this a retrieval failure? Becomes a query. Then a trend. Then an alert that fires before a customer runs the test for you.
Start small, ship value at each step
You do not need everything above on day one, and trying to build it all at once is how the project stalls. There is a natural order, and each step pays for itself before the next begins.
- First, capture document IDs and similarity scores at the search step. This alone makes most retrieval failures visible, because now you can answer what did retrieval return for any bad answer. It is the highest-value, lowest-effort move, and it is often a configuration change rather than new code.
- Second, add document freshness. Staleness is one of the most common retrieval failures and one of the easiest to detect once you record when documents were last modified and indexed.
- Third, add groundedness scoring on a sample. This is where you separate retrieval failures from model failures systematically rather than case by case, and it is the input your correctness SLO will want.
- Fourth, build the trends and alerts. Once the per-request signals are flowing, trending them is straightforward, and the alerts are what move you from reactive debugging to catching degradation early.
Each step leaves you better off than before and none of them requires the next, which means you can stop at any point with a working improvement and resume when there is appetite. That is the opposite of the all-or-nothing instrumentation project that never ships.
Where this sits
Retrieval telemetry is one of the five signals that make an AI system observable, and for RAG-heavy systems it is frequently the one with the highest return, because it illuminates the failure domain everyone else is flying blind through. It does not stand alone: the same instrumentation that captures retrieval spans carries the conversation traces and feeds the quality scores that make the whole picture coherent. Build it on the open standard, start with document IDs and scores, and grow it one self-justifying step at a time.
If you want to know whether your retrieval pipeline is currently visible or dark, the fastest read is the five-bad-answers test from the companion piece: pull five bad answers and see if you can find what retrieval returned. If you cannot, this how-to is your build plan. Our three-minute self-assessment scores retrieval visibility alongside the other four signals if you would rather start with the map than the territory; either way, the work is more tractable than the silence around it suggests.
Frequently asked questions
How do you instrument a RAG retrieval pipeline?
Model retrieval as a trace, not a black box: a sequence of spans for embedding, search, reranking, and context assembly, all children of the conversation trace. Instrument each step with the OpenTelemetry gen_ai conventions and link the spans to the downstream model call so a bad answer unrolls into its full causal chain.
What should you capture at the search step?
The document identifiers returned, their similarity scores, the number of candidates, store latency, which index or collection was queried, and any filters applied. Filters matter most: a permissions or metadata filter quietly excluding the best documents is a classic silent retrieval failure.
What is the highest-value first step for retrieval observability?
Capturing document IDs and similarity scores at the search step. It alone makes most retrieval failures visible, because you can finally answer what did retrieval return for any bad answer, and it is often a configuration change rather than new code.
Should you use the OpenTelemetry standard or a custom schema?
The standard. Telemetry on the OpenTelemetry gen_ai conventions is portable: it flows into any compatible backend, feeds automated evaluation later without rework, and survives your next tooling decision. A bespoke schema works only with the code that emits it, which is the lock-in trap in miniature.
About the Author
Brad Bell is the Principal Observability Lead at TekStream Solutions, a Digital Resilience partner that helps organizations operate, recover, and adapt with confidence by modernizing, securing, and optimizing their digital environments. His 29 years of experience spans large-scale telecommunications infrastructure, enterprise cloud strategy, and operational transformation across industries ranging from financial services to quick-service restaurants — work that included scaling monitoring platforms to 12,000+ nodes, architecting next-generation networks, and turning reactive ops teams into reliability engineering organizations. A Grafana Certified Solutions Architect and PreSales Solution Architect, he teaches SRE immersion courses at major financial institutions and consults on observability strategy at the enterprise level, helping clients navigate the convergence of cost pressure, tool sprawl, and AI-driven operations that is reshaping how enterprises think about reliability. His perspective isn’t theoretical — it comes from having been the person on the other end of a 2 AM page, and from watching organizations make expensive, avoidable mistakes with their observability investments. At TekStream, his focus is helping enterprises build platforms that solve today’s problems and hold up against where the industry is headed.