













An Honest Comparison of AI Observability Tools
By Brad Bell, Principal Observability Lead
Most teams evaluating AI observability tools start by building a feature matrix: five products down the side, twenty capabilities across the top, checkmarks in the cells. Then they pick the row with the most checkmarks and wonder, six months later, why the tool they chose cannot do the one thing they actually needed.
The matrix is the wrong instrument, because it assumes the five tools are competing for the same job. They are not. Two of them are production observability platforms, three are engineering workbenches, and asking which is best is like asking whether a torque wrench beats a multimeter. The honest comparison starts by sorting the tools into the jobs they actually do, and only then asking which one fits yours.
We implement and advise across all five, and we have no stake in steering you toward any of them. Where a tool we frequently deploy is behind, you will read that here, because a comparison that shades the evidence is worthless to you and to us.
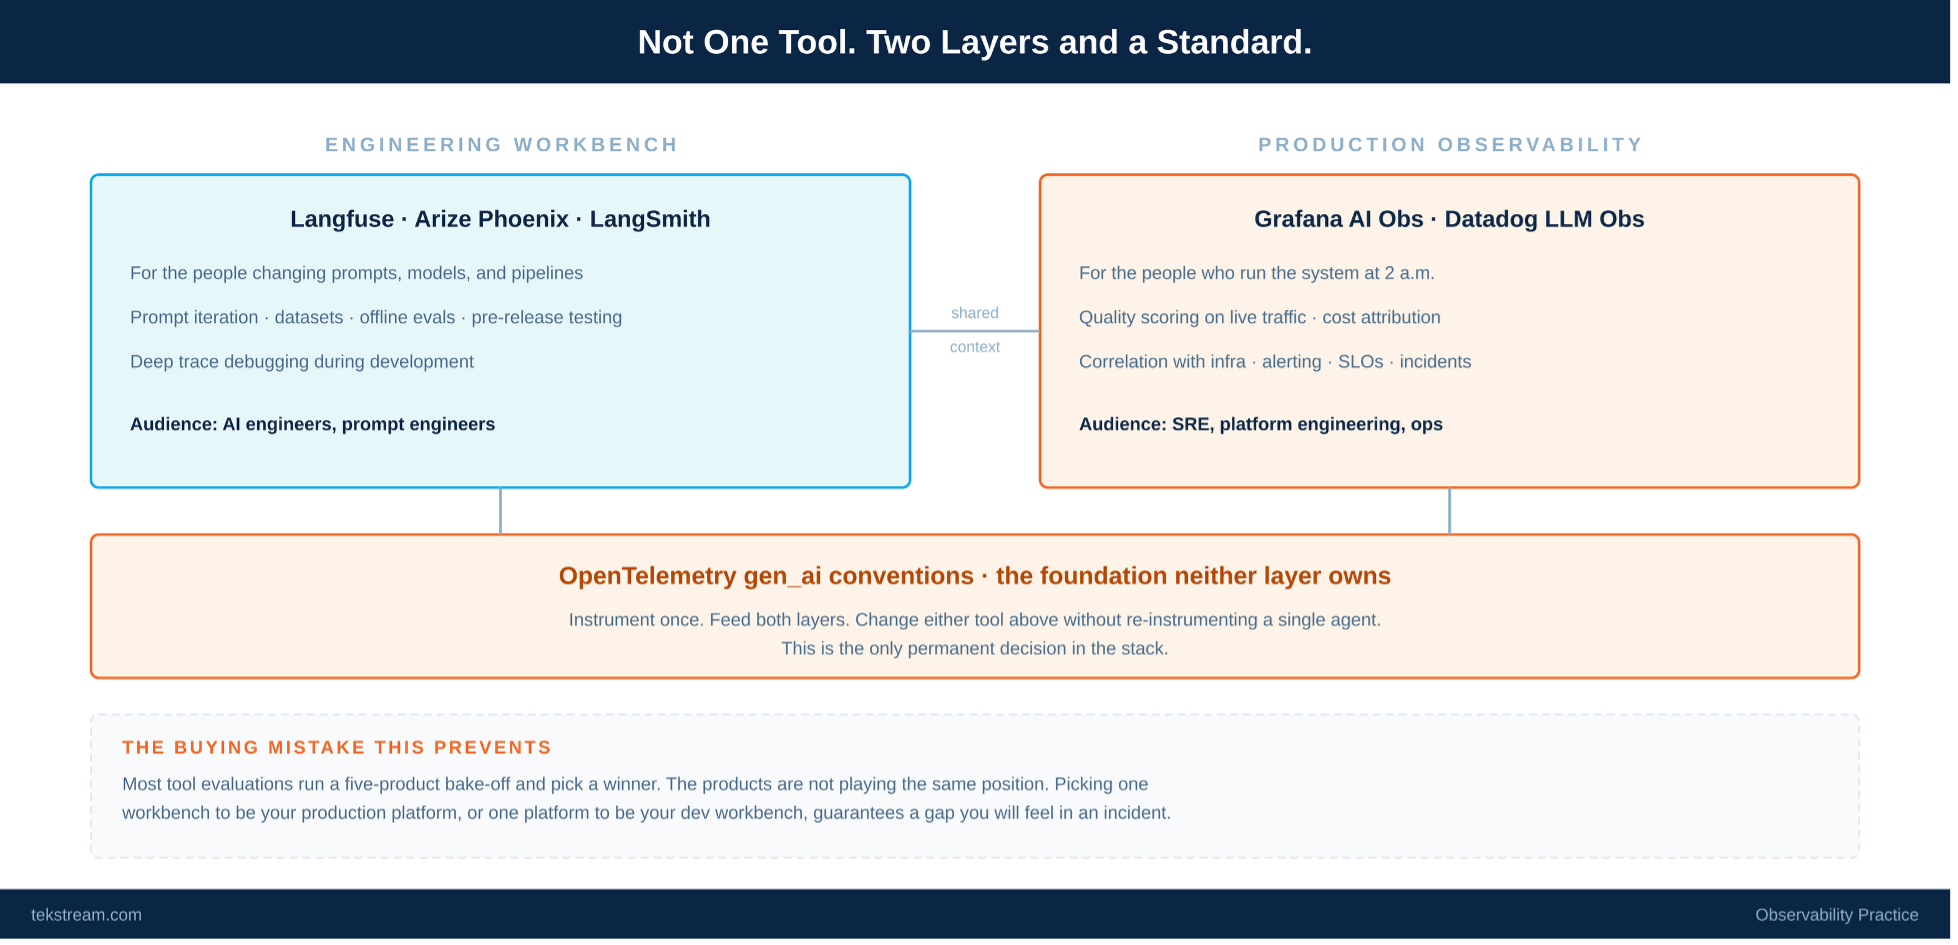
The split that organizes everything
Production observability platforms answer a question for the people running the system right now: is our AI healthy, accurate, and affordable, in correlation with everything else we operate? They live where your SREs already work, they correlate AI signals with infrastructure, and they carry the alerting, SLO, and incident machinery you run production on. Grafana AI Observability and Datadog LLM Observability are the two in this comparison.
Engineering workbenches answer a question for the people building the system: does this next prompt, model, or pipeline change make things better or worse before it ships? They are built for iteration, experimentation, and deep offline debugging. They do not correlate with your infrastructure, they do not replace production operations, and all three are excellent at the job they actually do. Langfuse, Arize Phoenix, and LangSmith are the workbenches here.
Hold that distinction and the rest of this is straightforward. Lose it and you will spend a quarter discovering that your beloved dev workbench has no concept of an SLO, or that your production platform makes prompt iteration miserable.
The production platforms
Grafana AI Observability is the only product in this group built on open standards from the first line of instrumentation. Traces and metrics ship as standard OpenTelemetry, generation data flows through a dedicated path so conversations join with traces, costs, and quality in one view, and it runs in the cloud or fully self-managed inside your boundary. Two capabilities stand out for enterprises: guard rules that evaluate on the request path before the model call, and content capture modes that let you choose full, redacted, or metadata-only logging per workload, which is the control a regulated environment needs before it can log generations at all. The honest caveat: it is in public preview while the others are generally available, and its evaluation workflow depth currently trails the best of the group. We say so plainly. What you are really buying is the OpenTelemetry foundation underneath, which is the part you cannot retrofit later.
Datadog LLM Observability is the deepest commercial product in the category and has been generally available the longest. Its quality-review workflow, pairing automated trace routing with structured human annotation, is currently the best available, full stop. If your organization already lives in Datadog, the integration between AI telemetry and your existing infrastructure, APM, and security views is genuinely excellent. The structural caveat: full value requires full Datadog (their tracer, their ingest, their pricing) as another line on a bill that is often already a budget’s fastest-growing item, and the instrumentation is Datadog-shaped, so the telemetry investment is not portable if your platform strategy changes. There is also no self-hosted option, which removes it from some regulated logging postures. We cover the agent-monitoring specifics in a companion piece.
The workbenches
Langfuse is the most widely adopted open-source option: tracing, evaluation, prompt management with versioning and rollback, datasets, and a playground in one coherent platform. It ingests OpenTelemetry, self-hosts in minutes, and its usage-based pricing avoids per-seat multiplication. Its prompt management, treating prompts as versioned deployable artifacts, is a discipline most AI teams lack and it makes adopting that discipline easy. What it does not do is production operations: no infrastructure correlation, no SLOs, no incident path. Worth knowing for planning: Langfuse was acquired by ClickHouse in January 2026, a natural technology fit that, like any acquisition, introduces roadmap questions worth asking before a multi-year commitment.
Arize Phoenix has the strongest retrieval and RAG evaluation tooling of the five, which matters because retrieval is where most RAG systems actually fail. Built-in evaluators cover faithfulness, relevance, and hallucination; embeddings analysis surfaces clusters and outliers no other tool here shows; and it is built on OpenTelemetry through conventions that are converging with the gen_ai standard. It runs locally in one command and fits notebook-first workflows unusually well. Its limits: production operations again, thinner cost attribution, and a span-tree-first trace experience that suits engineers more than reviewers. Teams that outgrow it typically graduate to Arize’s commercial platform, which is worth planning for rather than discovering.
LangSmith is the path of least resistance if your stack is LangChain or LangGraph: tracing in two lines of config, unmatched integration depth, and visual agent-graph debugging no other tool replicates. Its evaluation and dataset features are mature. The caveats: it is closed source with self-hosting reserved for enterprise agreements, its per-seat-plus-traces pricing inflates faster than teams expect under dense agent workloads, and its instrumentation leans proprietary, so of the five it ties your telemetry most tightly to one ecosystem. Outside LangChain, its advantage largely evaporates.
When to reach for which
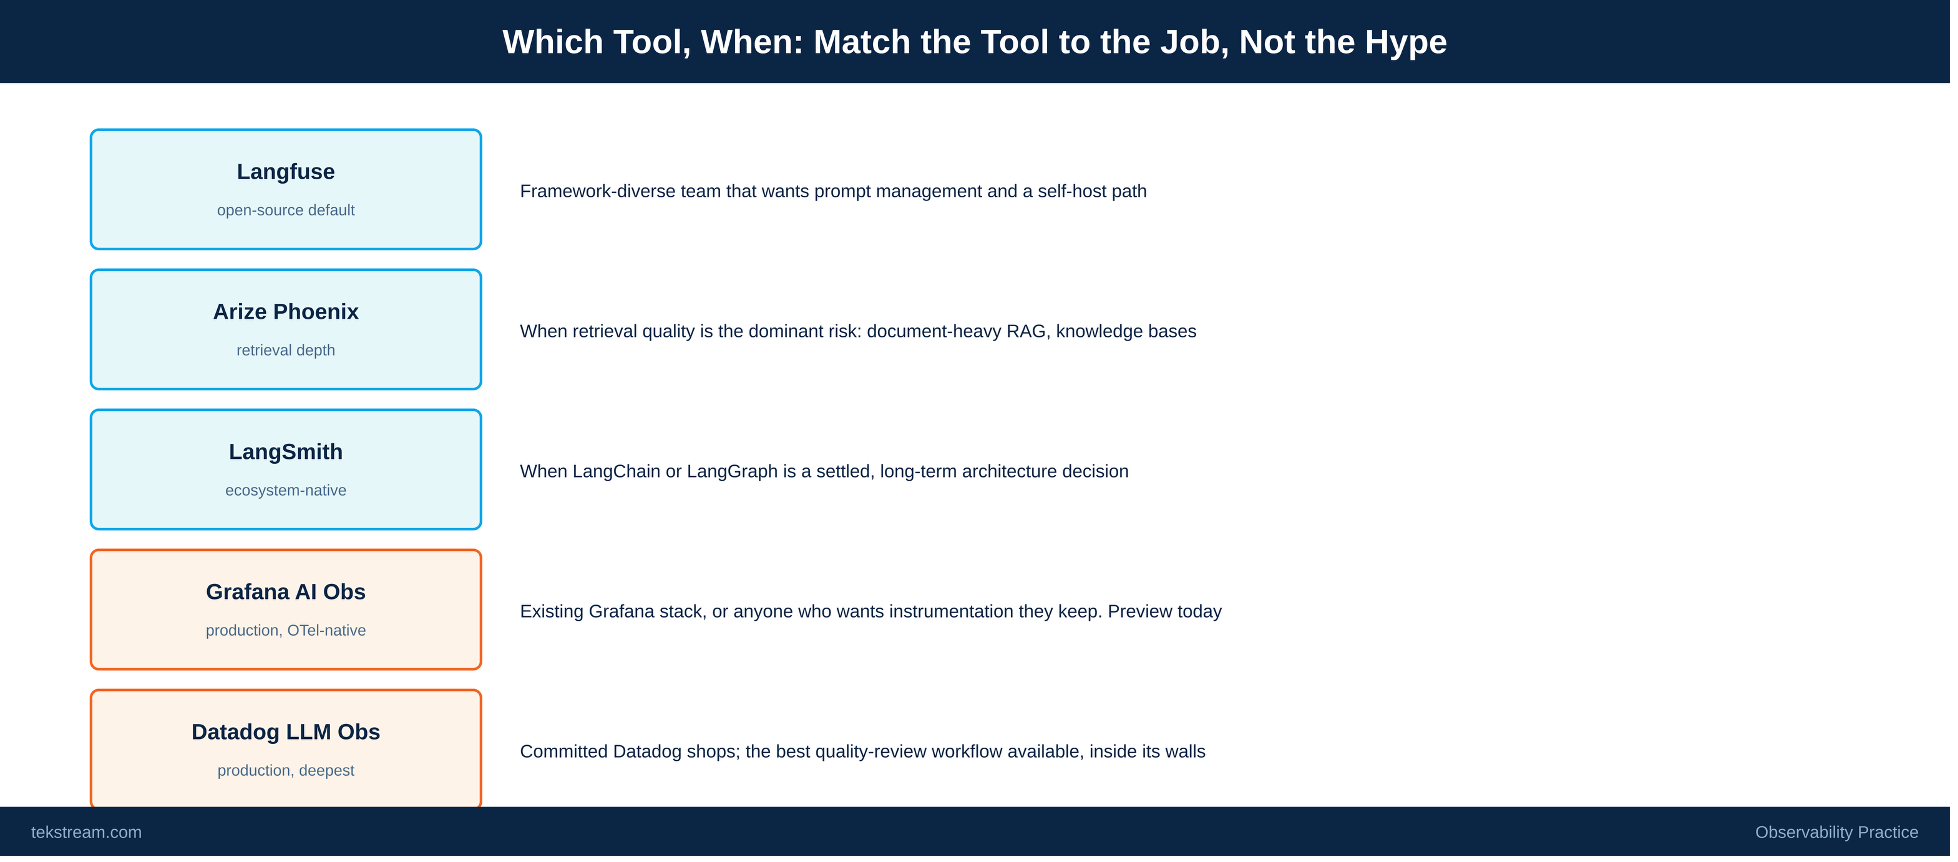
The architecture we recommend almost everywhere pairs one workbench with one production platform on a shared OpenTelemetry foundation. Your AI engineers get the iteration workflow they want; your operations team gets AI signals in the platform where they already run incidents; and a production quality alert links straight to the development trace that reproduces it. The combinations that come up most: a Grafana stack already in place pairs Langfuse with Grafana AI Observability for the lowest total friction. RAG quality as the dominant risk pairs Phoenix with a production platform. A committed LangChain shop pairs LangSmith with standards-based production instrumentation. And a regulated environment that cannot let generation data leave the building runs a self-hosted workbench under a self-managed platform, every component inside the boundary.
The decision under the decision
Here is the part the feature matrix can never show you, and it is the only part that is permanent. The tools above will change. Two of the five independents in this space were acquired in the last year; Langfuse went to ClickHouse, and a strong evaluation platform called Galileo is being folded into Splunk by Cisco. Tools change owners, names, roadmaps, and pricing. The one layer that does not is the instrumentation standard underneath them.
Instrument your AI workloads once, on the OpenTelemetry gen_ai conventions, and every tool in this comparison can consume that telemetry. Change your mind about any of them and the instrumentation stays. Own that layer and the tool decision stops being a one-way door; skip it, instrument on a proprietary SDK, and you negotiate your next renewal from a weak position. In our experience the teams that struggle most in eighteen months will not be the ones that picked the wrong tool. They will be the ones whose telemetry is trapped inside whichever platform bought it.
So make the tool choice that fits your job, using the split and the pairings above. But make the instrumentation choice first, and make it open, because it is the only choice here you cannot easily reverse. If you want a structured way to figure out which combination fits your environment, our three-minute self-assessment scores your coverage across the five signals and maps your current tools against this architecture; it is a fair place to start, with us or on your own.
About the Author
Brad Bell is the Principal Observability Lead at TekStream Solutions, a Digital Resilience partner that helps organizations operate, recover, and adapt with confidence by modernizing, securing, and optimizing their digital environments. His 29 years of experience spans large-scale telecommunications infrastructure, enterprise cloud strategy, and operational transformation across industries ranging from financial services to quick-service restaurants — work that included scaling monitoring platforms to 12,000+ nodes, architecting next-generation networks, and turning reactive ops teams into reliability engineering organizations. A Grafana Certified Solutions Architect and PreSales Solution Architect, he teaches SRE immersion courses at major financial institutions and consults on observability strategy at the enterprise level, helping clients navigate the convergence of cost pressure, tool sprawl, and AI-driven operations that is reshaping how enterprises think about reliability. His perspective isn’t theoretical — it comes from having been the person on the other end of a 2 AM page, and from watching organizations make expensive, avoidable mistakes with their observability investments. At TekStream, his focus is helping enterprises build platforms that solve today’s problems and hold up against where the industry is headed.